About Semantic Encoder (SE)
About Semantic Encoder (SE)


|
|
What is a Semantic Encoder (SE) model
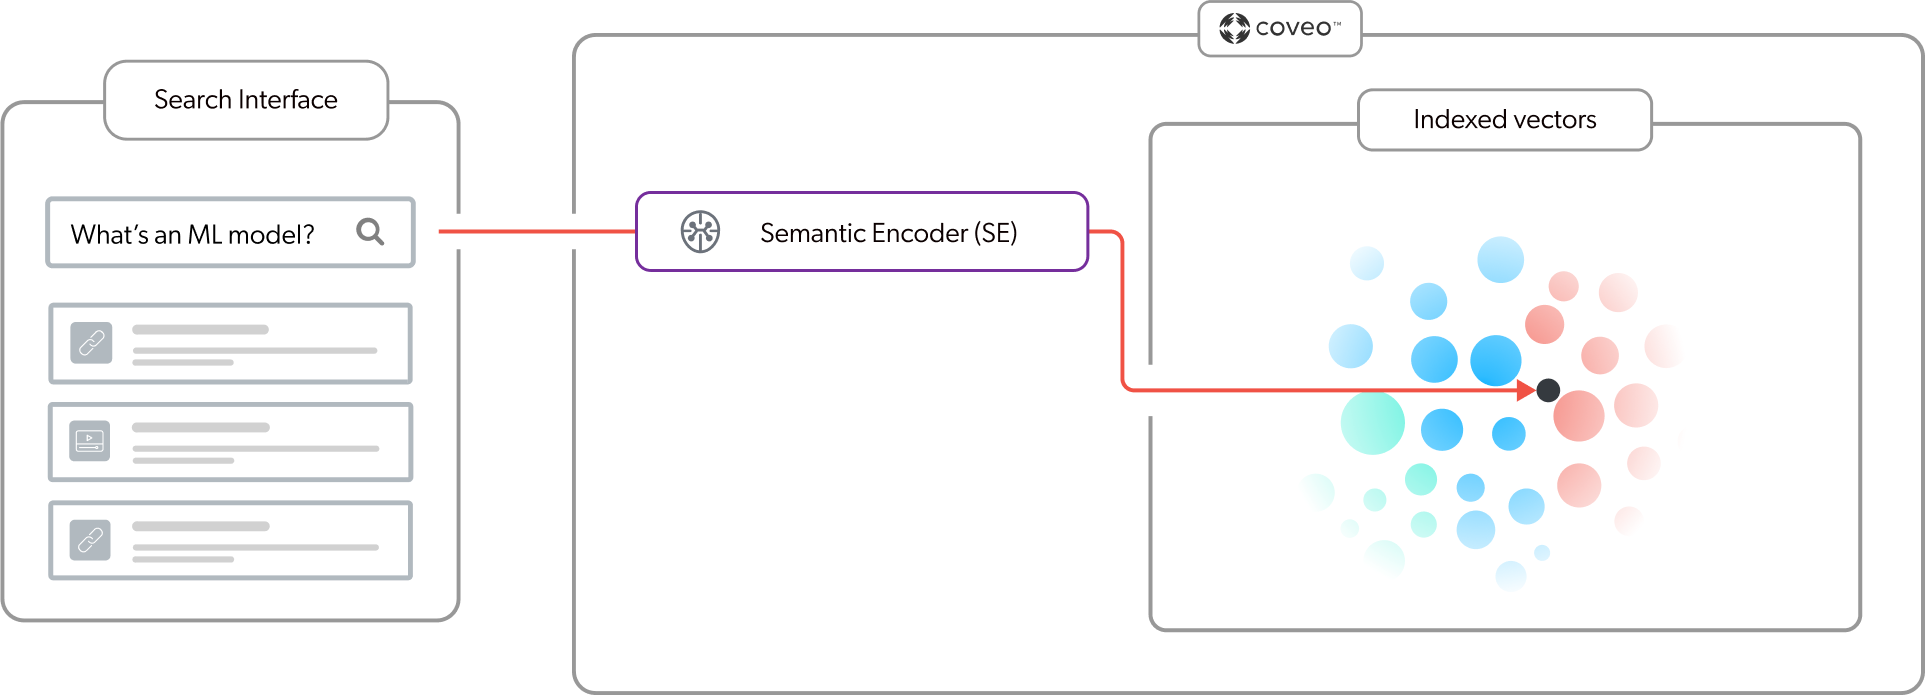
A Semantic Encoder (SE) model uses vector search to retrieve items from your index based on their semantic similarity to the query. It first creates embeddings for the enterprise content you specify, then uses those embeddings at query time to identify relevant items.
Traditional lexical (keyword) search matches words and phrases in a query with those in items. In contrast, vector-based search finds items that are similar in meaning, even when they don’t share the same keywords.
As generative AI reshapes customer expectations, search interfaces must support increasingly complex natural language queries. An SE model helps retrieve items that reflect the context and intent of these queries. It works alongside traditional lexical search, combining semantic similarity with keyword matching to retrieve the most relevant items.
When to use the SE model
An SE model is used as part of an RGA or CPR implementation, where it helps the RGA or CPR model work from the most relevant content when generating answers or retrieving passages.
Each query passes through a query pipeline where pipeline rules and machine learning are applied to optimize relevance. When the SE model is used in a query pipeline, search combines traditional lexical (keyword) search with vector-based search to retrieve items from the index based on keyword matches and semantic similarity to the query. Both the SE model and traditional lexical search contribute to the final search results, each influencing which items are retrieved.
In an RGA implementation, the SE model helps retrieve relevant items that the RGA model uses to generate answers (see How RGA generates answers). In a CPR implementation, the SE model helps to retrieve relevant items from which the CPR model extracts passages. Depending on your implementation, the passages are then used by the Coveo Search Agent to generate answers in your Coveo-powered search interface, or retrieved through the Passage Retrieval API and provided as input to your enterprise’s own LLM-powered application. For more information, see When to use CPR.
In both cases, vector-based retrieval helps surface content that matches the meaning and intent of complex natural language queries, even when the content uses different keywords.

|
By default, content retrieval is supported only for English content. However, Coveo offers beta support for content retrieval in languages other than English. Learn more about multilingual content retrieval and answer generation. To view the model’s current language support setting, access the model’s Information tab. |
SE model processes
Embeddings
Embedding is a machine learning technique used in natural language processing (NLP) to convert text data into numerical representations (vectors) mapped to a vector space. The vector space can represent the meaning of words, phrases, or documents as multidimensional points (vectors). Therefore, vectors with similar meaning occupy relatively close positions within the vector space. Embeddings are at the core of vector-based search, such as semantic search, that’s used to find similarities based on meaning and context.
The following is a representation of a vector space with each dot representing a vector (embedding). Each vector is mapped to a specific position in the multi-dimensional space. Vectors with similar meaning occupy relatively close positions.
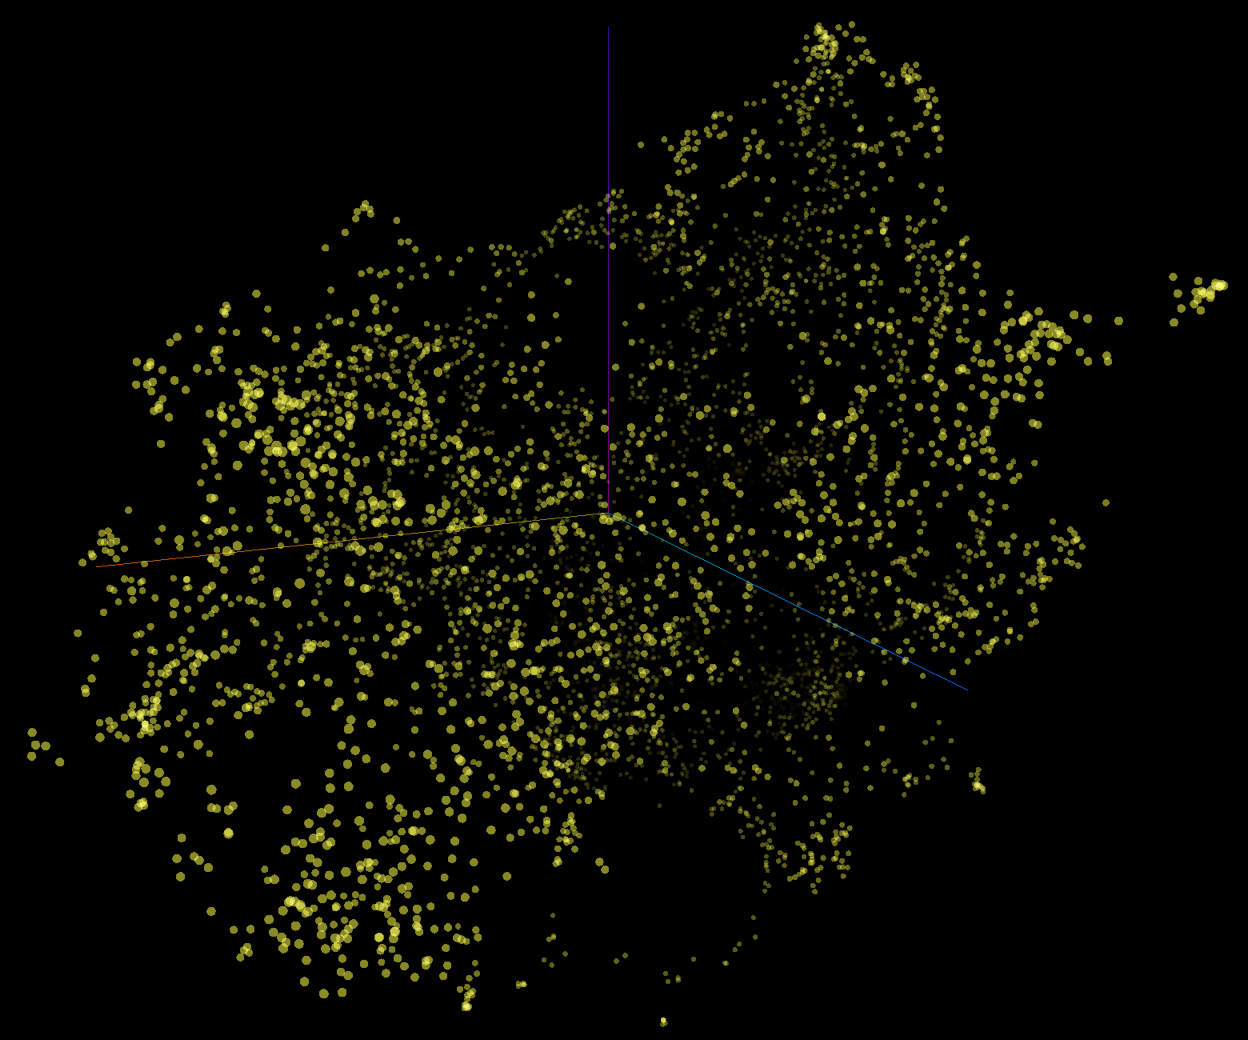
A Semantic Encoder (SE) model creates and uses its own embedding vector space. The model has the dual purpose of creating the embeddings, and then referencing its vector space at query time to retrieve relevant content.
The SE model uses a pre-trained sentence transformer language model to create the embeddings. The model creates the embeddings when it builds, and then updates the embeddings based on its build schedule. For more information, see What does an SE model do?.
Chunking
Chunking is a processing strategy that’s used to break down large pieces of text into smaller segments called chunks. The SE model uses chunks to create the embeddings. Each chunk is mapped as a distinct vector in the embedding vector space.
An SE model uses an optimized chunking strategy to ensure that a chunk contains just enough text and context to be semantically relevant.
When an SE model builds, the content of each item that’s used by the model is broken down into chunks that are then mapped as individual vectors.
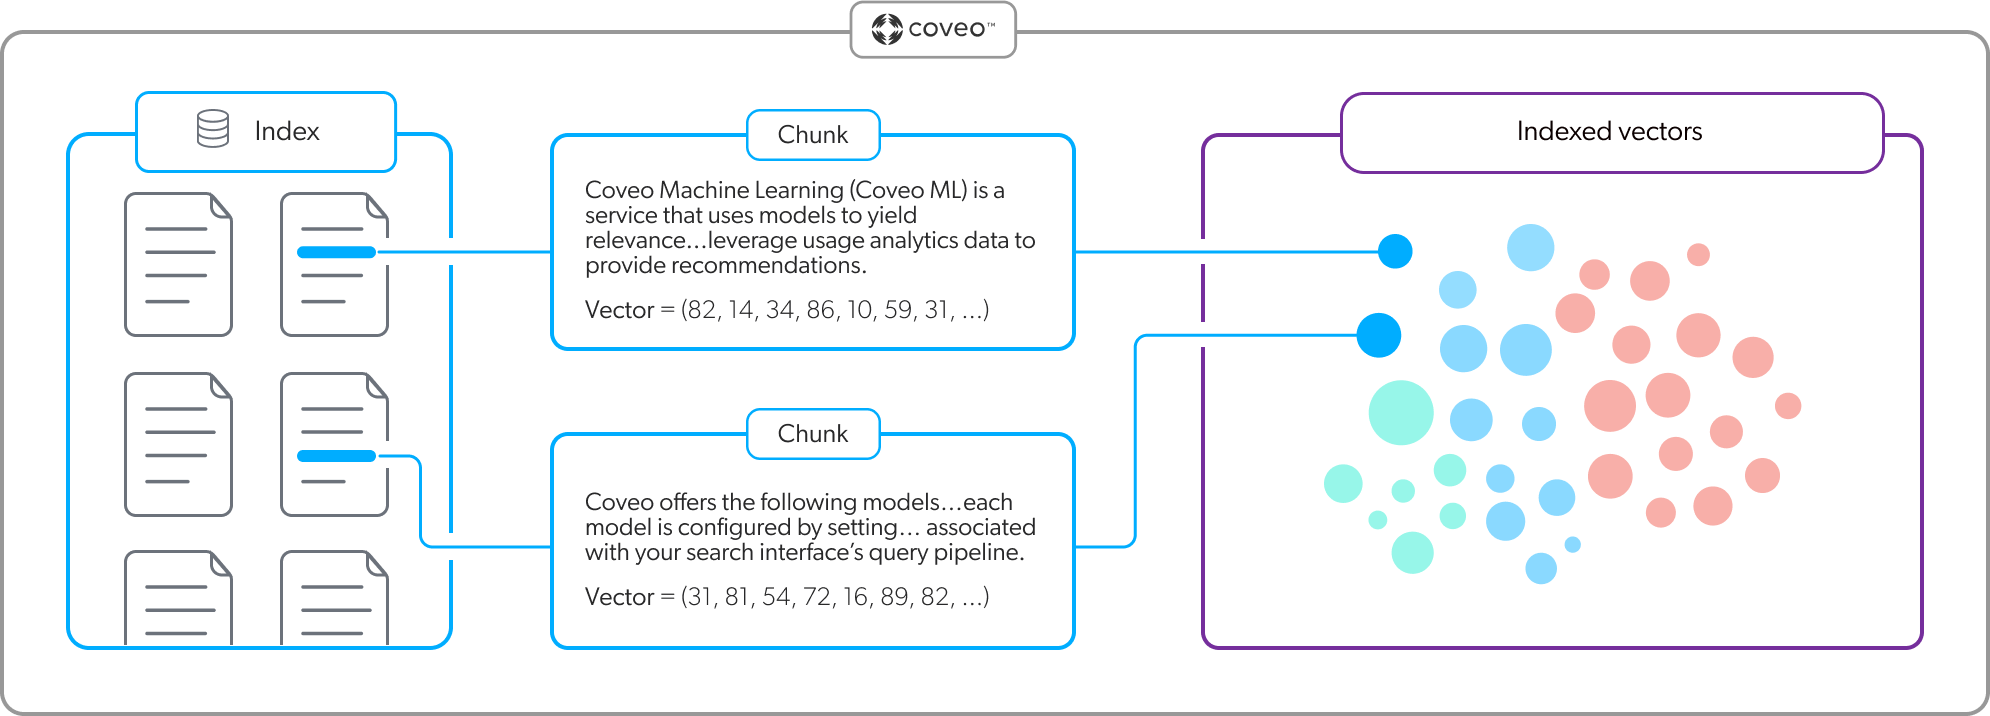
An effective chunking strategy ensures that when it comes time to retrieve content, the model can find the most contextually relevant items based on the query.

|
Note
Semantic Encoder (SE) models are subject to chunking constraints. For more information, see the SE embedding constraints. |
Relevant content retrieval
An SE model is used in the first of two content retrieval stages in an RGA or CPR implementation. These stages help identify the most relevant content for answer generation or passage retrieval.
|
|
Note
Your enterprise content permissions are enforced during content retrieval. This ensures that authenticated users only see the information that they’re allowed to access. |
-
First-stage content retrieval identifies the most relevant items in the index.
-
Second-stage content retrieval identifies the most relevant chunks (passages) from the most relevant items retrieved during first-stage retrieval. The RGA or CPR model performs this retrieval stage.
|
|
By default, content retrieval is supported only for English content. However, Coveo offers beta support for content retrieval in languages other than English. Learn more about multilingual content retrieval and answer generation. To view the model’s current language support setting, access the model’s Information tab. |
First-stage content retrieval
First-stage content retrieval occurs at the item level, where the Coveo search engine identifies the most relevant items in the index for a given query. Each query passes through a query pipeline, where rules and machine learning help optimize relevance. When an SE model is associated with the query pipeline, it uses vector search to retrieve semantically relevant items.
For a given query, the SE model embeds the query into the vector space to find the items with high semantic similarity with the query.